
SHORT ANSWER
Data mesh is a way of organising analytical data in which business domains own and publish their data as products, instead of one central data team owning everything. It rests on four principles: domain ownership, data as a product, a self-serve data platform and federated computational governance. It usually pays off only when a central team has become a bottleneck across several domains.
Data mesh is a decentralised approach to analytical data. The business domains that create data (sales, supply chain, finance and so on) publish it as well-described, reliable data products. A central platform team provides the tools, and a federated group sets shared standards. Zhamak Dehghani introduced the idea in 2019.
How does data mesh work?
Data mesh rests on four principles:
Domain ownership: each domain owns its analytical data end to end, from ingestion to quality.
Data as a product: datasets are designed for their consumers, with owners, documentation, SLAs and data contracts.
Self-serve data platform: a platform team offers storage, pipelines, catalog and security as reusable services.
Federated computational governance: shared rules for security, naming and interoperability are agreed centrally and enforced automatically in the platform.
Why does it matter for enterprises?
In large organisations a central data team often turns into a queue. Every new source or report waits for the same few engineers, who don’t know the business context. Data mesh moves responsibility to the people who understand the data, which can shorten delivery times and raise quality. The price is more coordination, a stronger platform and clear governance. It usually suits companies with several independent business units and dozens of data engineers.
Centralised platform vs. data mesh
| Centralised data platform | Data mesh |
|---|---|---|
Who owns the data | Central data team | Business domains |
Unit of delivery | Tables and pipelines | Data products |
Governance | Central team decides | Federated, automated policies |
Bottleneck risk | High as demand grows | Lower, but needs coordination |
Best fit | One business unit, small teams | Many domains, mature data culture |
We saw the self-serve principle up close on a data and analytics portal we built for a global chemical and consumer goods company whose data platform follows the mesh pattern. The platform team supplied the tooling, but people still needed one place to discover data products, request access and create new ones. Those processes crossed many services, so we ran an Event Storming session to map the data product lifecycle with the client before we built it.
Start small. Pick two or three domains with motivated owners, publish their first data products on your existing platform and agree a minimal set of standards for naming, quality checks and access. Expand only after those domains deliver faster. Companies that announce a company-wide mesh on day one often end up with renamed tables and no real change in ownership.
How RUBICON helps with data mesh
We design data platforms on Databricks and Microsoft Fabric, and we use Event Storming to make domain boundaries visible. If you’re not sure a mesh fits, our architects can help you test it against your current setup.
Related terms
Frequently asked questions
Who invented data mesh?
Zhamak Dehghani introduced data mesh in 2019, while she was at Thoughtworks, and described it in detail in her 2022 book on the topic. It borrows ideas from domain-driven design and product thinking and applies them to analytical data, as a response to the bottlenecks of central data lake and warehouse teams.
Is data mesh a technology or a tool?
No. Data mesh is an organisational and architectural approach, not a product. Teams usually build it on platforms they already run, such as Databricks, Microsoft Fabric or Snowflake, using catalogs, workspaces and access policies. Vendors may market mesh features, but the hard part is changing ownership, incentives and governance.
What is the difference between data mesh and data fabric?
Data mesh is mainly about people and ownership: domains publish data products. Data fabric is mainly about technology: a metadata-driven layer that connects data across systems, often with automation. The two can coexist, with a fabric-style platform providing the self-serve tools that mesh domains use.
When is data mesh not a good fit?
Data mesh adds overhead, so it rarely pays off for smaller companies, a single business unit or organisations with only a handful of data engineers. If your central team isn't a bottleneck yet, a well-governed central lakehouse with clear data products is usually simpler and cheaper to run.
Related case study
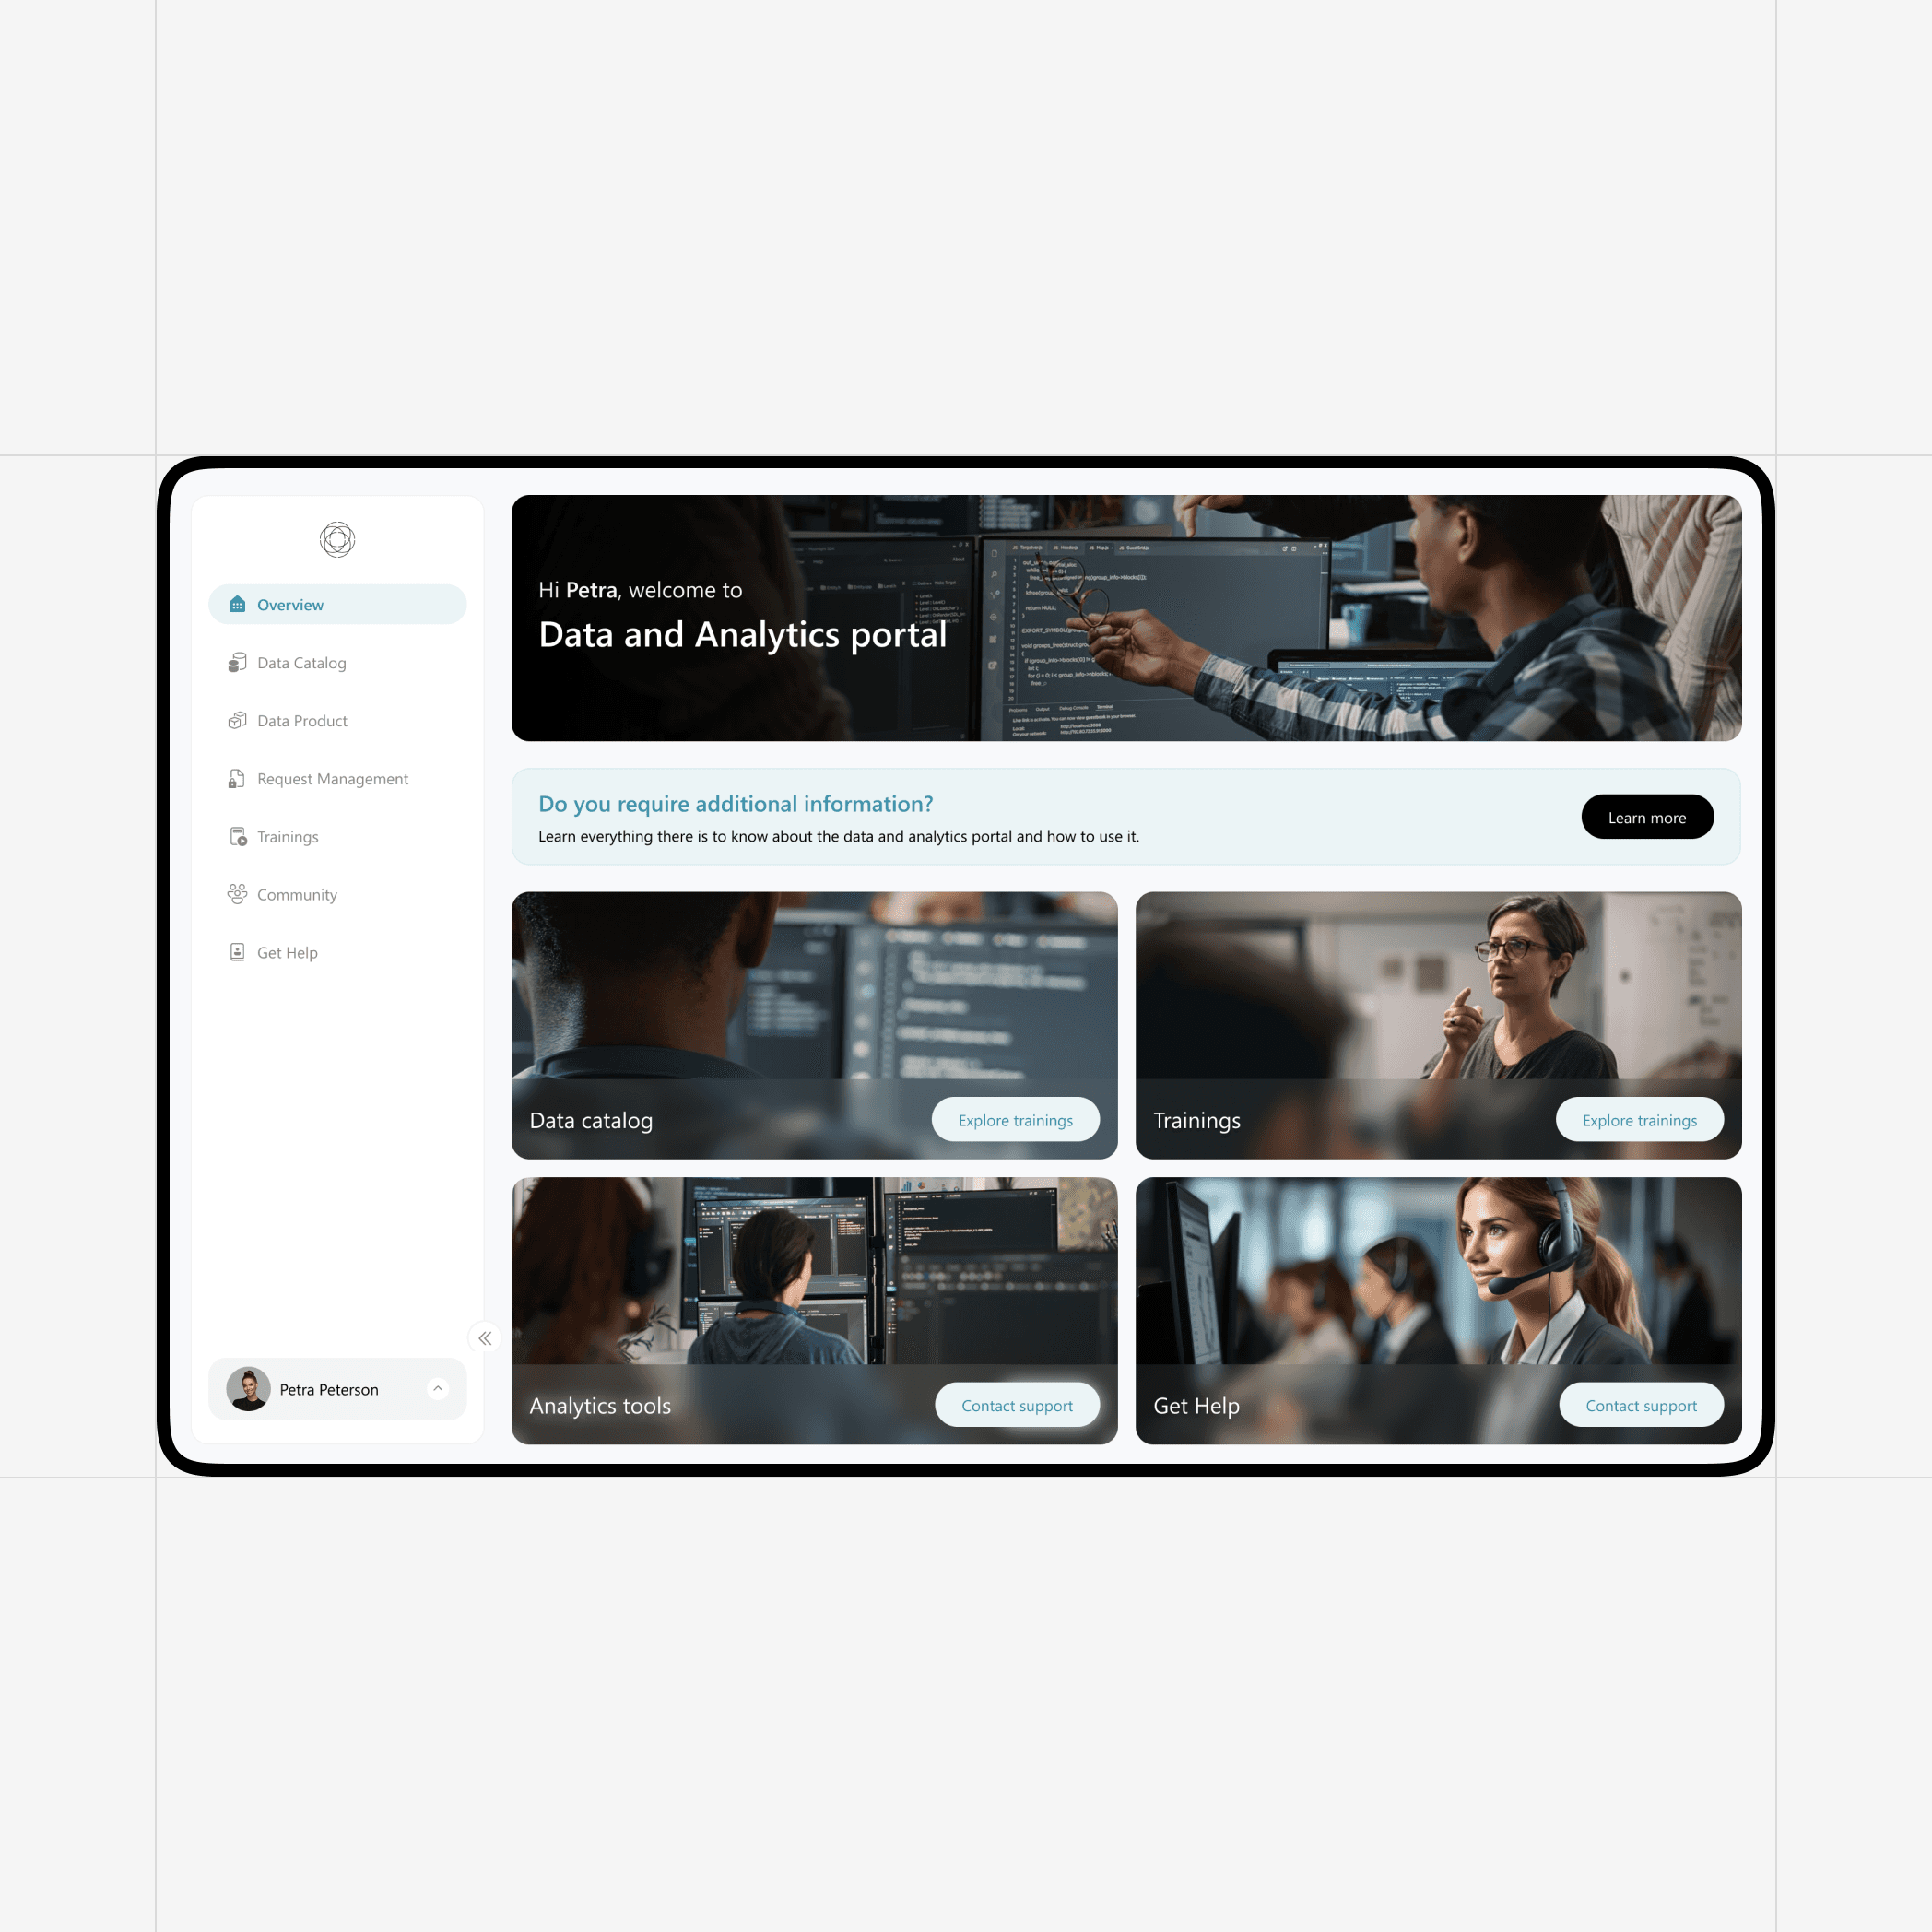
Enterprise Data Hub: All in One Analytics Portal
RUBICON delivers a comprehensive and secure cloud-based solution that serves as a single entry point for data consumers, bringing together all elements of data platform and analytics needs.
More resources



